Jev: the AI model that returns decisions instead of text
With Jev, TypeSafe introduces a model that does not generate text, but makes typed, probabilistic decisions. This unlocks new possibilities and speeds for automated agentic workflows, though independent broad benchmarks are still lacking.
For years, the world of generative artificial intelligence has revolved almost exclusively around text. Models write complex programming code, draft nuanced emails, and generate page-long reports. But as AI becomes more deeply integrated into advanced automation tasks, a fundamentally different need arises: the demand for extremely fast, reliable, and machine-readable decisions. In many business processes, a full essay as an answer is redundant; systems only require a highly structured outcome. Recently, after more than two years in stealth, the startup TypeSafe launched their definitive answer to this specific problem. Their new model, named Jev, is currently available in early access. Backed by a $40 million funding round led by investment firm DCVC, founders Diogo Almeida, Erik Gafni, and Sasha Sheng promise a significant paradigm shift in how we design and deploy AI agents.
The shift from text generation to robust decision-making
To fully grasp why the launch of Jev is remarkable, we must look at the current state of AI engineering. When building reliable systems, data engineers and developers currently spend an enormous amount of time curbing the creativity of mainstream models. Traditional autoregressive models like GPT-4 and Claude are designed for broad, complex generative tasks. They predict text token by token. This makes them highly versatile, but simultaneously less efficient for simple binary or multiple-choice decisions. They are simply relatively slow and computationally expensive when the required output only needs to consist of a 'yes', a 'no', or a specific category label.
Developers currently solve this by forcing the model—using intricate prompts and strict JSON schemas—to return a predictable answer. However, this process still requires the model to undergo the full autoregressive cycle under the hood. The model has to "think" about the first token, the second token, the quotation marks, and so on. This introduces inevitable latency and drives up costs, an issue that scales drastically as the workflow's complexity increases.
The Jev architecture and RLCD explained
Jev is a new type of AI model that does not generate text, but exclusively makes typed, probabilistic decisions based on a given context.
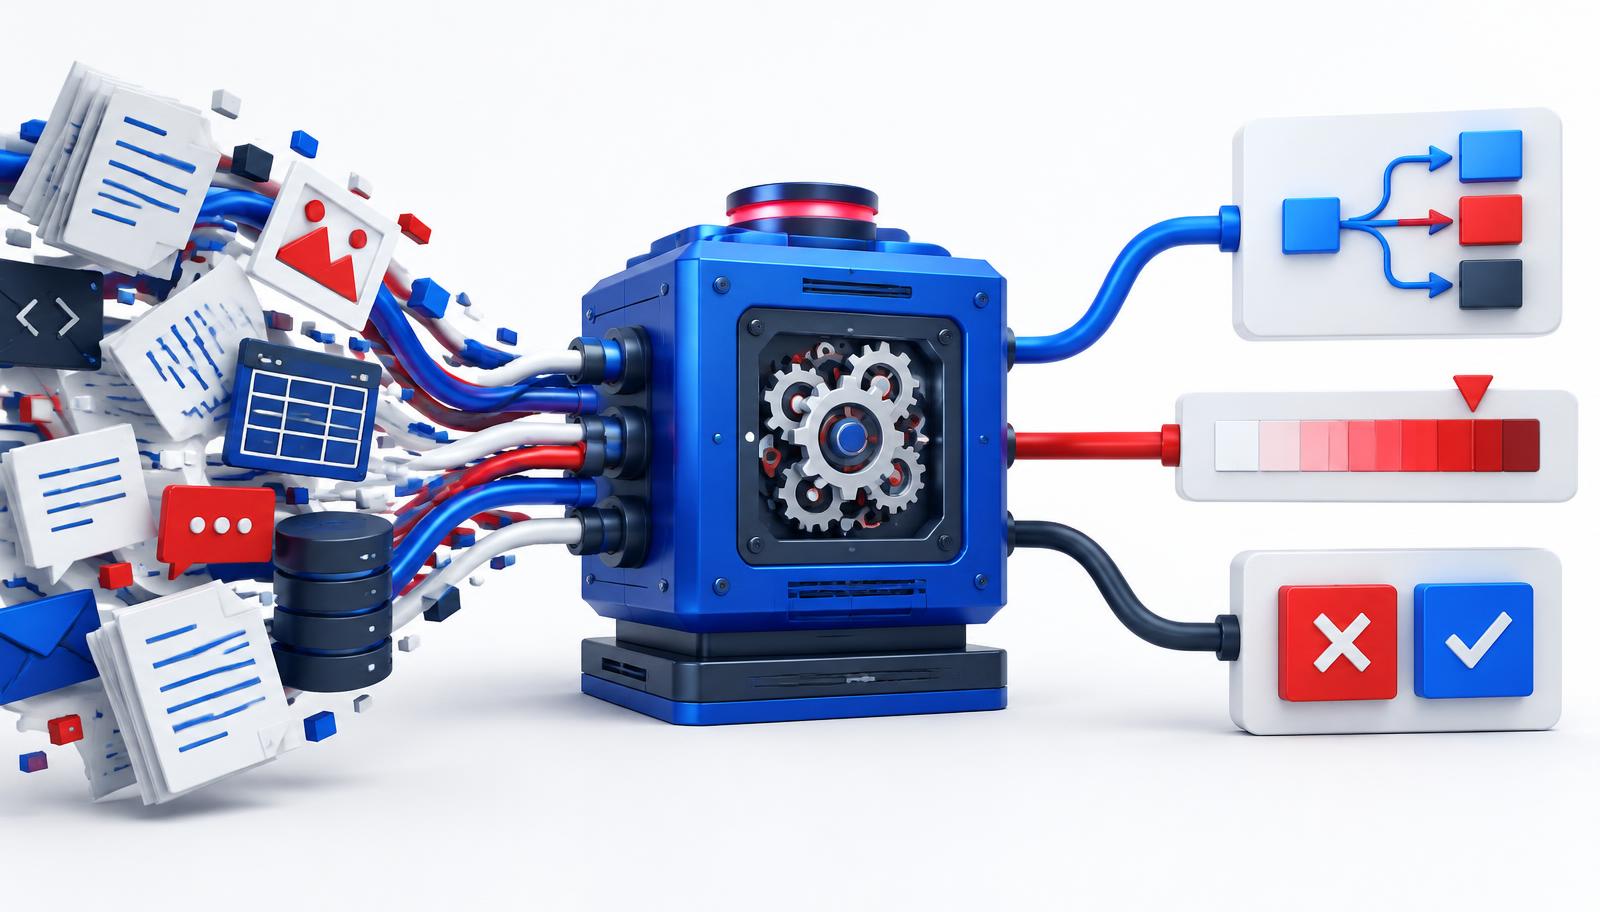
Jev tackles this fundamental bottleneck in a completely different way. The model categorically refuses to generate freeform text. Instead, developers provide Jev with a state (for example, the literal content of an incoming customer email, supplemented with customer metadata) alongside a fixed set of specific questions. Jev evaluates all these defined questions in parallel. This completely bypasses the latency inherently tied to sequential token generation.
To enable this parallel architecture, TypeSafe claims to utilize a 'parallel sampler' coupled with a unique training methodology they call Reinforcement Learning for Calibrated Decisions, or RLCD. Through RLCD, the model does not learn which word logically follows the previous one, but rather how to assign accurate probabilities to a predefined set of possible outcomes. Consequently, this means Jev performs no test-time reasoning. It does not pause to internally construct a multi-step chain of thought before answering. It is therefore specifically intended for fast, bounded judgments and explicitly not suited for highly complex reasoning tasks where intermediate logic steps are crucial.
The three API primitives: choice, score, and noul
To keep interactions with the model rigorously structured, Jev enforces the use of three strict data types (primitives) via its API. Because the underlying architecture operates in parallel, developers can effortlessly fire off multiple distinct questions about the same state without incurring a significant penalty in response time.
| Primitive | Description | Exact Output Format |
|---|---|---|
| Choice | Selects one specific, predefined option from a list determined by the developer. | The selected option, a probability distribution over all options, and a confidence score. |
| Score | Evaluates the input across a set of logically ordered levels (e.g., from extremely low to extremely high). | A fractional, weighted score (e.g., 3.2), the probabilities per level, and a confidence score. |
| Noul | A lightning-fast binary decision tailored for high-frequency situations. | Only a probability of 'true' (a precise value between 0 and 1). Noul does not return a separate confidence score. |
What a Jev request looks like
The actual interaction with Jev's gateway API differs fundamentally from regular chat APIs. There are no message arrays with 'user' or 'assistant' roles. Instead, you define the state as an object, use strictly lowercase data types, and provide exact instructions and criteria per question.
{
  "model": "typesafe/jev-latest",
  "state": {
    "customer_profile": "Premium subscriber, loyal customer for 3 years.",
    "message_text": "My order arrived severely damaged and I want my money back immediately, or I am canceling."
  },
  "questions": {
    "intent": {
      "type": "choice",
      "instructions": "Determine the main intent of this customer's message.",
      "criteria": {
        "return": "The customer wants to return a product or receive a refund.",
        "complaint": "The customer is dissatisfied with the provided service or delivery.",
        "cancellation": "The customer wants to terminate an existing subscription immediately."
      }
    },
    "urgency": {
      "type": "score",
      "instructions": "Assess how urgent this request is based on emotion and potential business risks.",
      "criteria": [
        "No rush, it is a standard and neutral request for information.",
        "Normal priority, requires action within the standard agreed SLA.",
        "Critical, the customer is clearly angry and threatening cancellation or further action."
      ]
    },
    "escalation_required": {
      "type": "noul",
      "instructions": "Should this ticket be immediately escalated to a senior human agent?",
      "criteria": {
        "true": "The customer explicitly threatens cancellation or expressed severe dissatisfaction.",
        "false": "This is a standard request without a direct threat of churn."
      }
    }
  }
}
Performance, latency, and the limits of benchmark claims
Through its absolute focus on decision-making over free text generation, Jev positions itself perfectly for enterprise processes where reliable structure and pure speed are paramount. To illustrate this impressive processing speed, TypeSafe showcased an experimental demo at launch where Jev actually plays the classic video game Doom. The model does this purely by classifying actions at lightning speed in real-time based on a structured, textual game state.
The current pricing and performance in this early access phase make it economically scalable. As vendor information, TypeSafe reports a current rate of $0.042 per million input tokens, with absolutely zero costs for output tokens given the concise nature of the results. Regarding latency, TypeSafe reports roughly 70 to 500 milliseconds of end-to-end response time per call. According to TypeSafe's own evaluations, this makes Jev up to 193.6 times faster and 444.6 times cheaper than traditional alternatives in specific agentic workflows. However, it is absolutely crucial to emphasize that these are explicit extremes, derived from TypeSafe's internal evaluations on highly specific tasks. Average results or performance on differing, complex tasks may vary wildly, and as of now, there is no independent, broad benchmark available in the market to definitively substantiate these massive claims.
Schema guarantees: what 'cannot hallucinate' really means
While the early launch understandably garners much attention, important nuanced voices and valid criticisms are also emerging within the AI community. In its marketing material, Jev claims the model "cannot hallucinate." For laypeople, this sounds like the ultimate holy grail, but it is exclusively a shape and schema guarantee. It means Jev cannot possibly output an answer or label outside the developer-defined options. Your code will therefore never crash due to an unexpected textual response. However, the model can still factually make the entirely wrong decision. An angry email could still accidentally be classified as a neutral question; the answer will fit neatly into the schema, but the decision itself is simply incorrect.
Furthermore, critical industry experts, such as AI developer Sean Goedecke, point out that large traditional models are becoming increasingly effective at reliably forcing structured output. By using the API to force a standard model to adhere to a restrictive JSON schema or grammar structure, you already achieve a fair portion of the predictability benefits today. Because Jev also lacks test-time reasoning, it quickly falls short for highly intricate routing puzzles. Consequently, the actual, long-term competitive moat remains difficult to verify independently.
The importance of group-wise calibrated confidence
One of Jev's most critical technical pillars is the emphasis on calibrated confidence scores for the outcomes of Choice and Score. But what exactly does calibration mean here? Please note: 'calibrated' in the context of the RLCD training means the model is strictly group-wise calibrated. It absolutely does not guarantee that one specific individual prediction is one hundred percent factually correct, even with a high score. It simply means that if you make ten thousand decisions over a longer period where the model firmly reports 90 percent confidence, exactly 90 percent of that specific group of decisions will indeed turn out to be correct. This is existential for a system's statistical reliability across the board, but provides no absolute factual certainty at the micro-level when evaluating one single customer email.
The Jevons paradox in agentic workflows
The extreme reduction in both cost and latency inevitably leads to a phenomenon known in theory as the Jevons paradox. When steam engines became more efficient and cheaper in their coal consumption due to technological advancements in the nineteenth century, the total global consumption of that coal paradoxically increased exponentially. Why? Because the lowered barrier suddenly unlocked countless new, profitable applications that were previously unthinkable or unaffordable.
Exactly this same principle now applies to AI decision-making. Why does a truly robust agentic workflow contain dozens of hidden decision points? Because ideally, every piece of incoming data should pass through multiple checkpoints, ethical classifications, and safety validations. As soon as making these micro-decisions costs practically nothing in terms of finance and wait time, organizations will massively integrate giant quantities of decisions per second into their processes. Think of the real-time routing of thousands of customer service tickets a day, automatically streamlining and classifying heavy logistical document flows, and extensive quality controls on the texts generated by other, slower AI models.
Our take: this fundamentally changes agentic workflows
At ai.nl, we build and analyze agentic workflows daily across established platforms such as Copilot Studio, CrewAI, LangChain, and n8n. In practice, we notice that latency and instability in the flow almost always arise at the exact moments the system has to decide: Should I call tool X or tool Y for this? Does this extracted text contain sensitive personal data (PII)? Is the newly generated summary factually accurate enough to send to the client?
If making these essential decisions truly and structurally becomes two orders of magnitude faster and cheaper, it forces a fundamentally new architecture for automation. It becomes operationally feasible to place extensive checks and tight guardrails at every single iterative step in a digital process. Moreover, because Jev returns genuinely calibrated probabilities and reliable confidence scores, these models allow for explicit, hard mathematical thresholds to be built into workflows. A concrete example policy in a ticketing system could be: a reported confidence above 0.95 triggers fully automatic processing without human intervention; a score between 0.70 and 0.95 escalates the task to a senior employee for review; and anything below 0.70 indicates too much ambiguity and is sent straight back to the triage queue. It is essential to emphasize that this is merely an abstract example policy, which must be rigorously validated and monitored per specific use case in your organization.
This leads us to a clear prediction. This is explicitly an opinion of ai.nl and not an established fact, but we see it loud and clear: TypeSafe's approach is so highly specialized, yet simultaneously so indispensable for the large-scale reliability of enterprise agents, that the company forms a highly logical and strategic acquisition target for a major frontier lab like OpenAI, Anthropic, or Google. After all, such entities are continuously seeking ways to make their own agent frameworks more robust.
Our practical advice to you as a builder? Do not wait to innovate until Jev or similar System One models are widely and generally available to critically examine your own workflows. Start inventorying today which existing, sluggish LLM calls in your systems actually end up in a brief judgment that fits in three words. Those are the exact spots where you will achieve massive efficiency gains the fastest in the near future.
Sources
- Official launch: Introducing System One Models and Jev (TypeSafe)
- TypeSafe API Primitives Documentation
- TypeSafe Concepts: System One & Confidence
- TypeSafe Internal Evaluations and Benchmarks
- Yahoo Finance / Business Wire: TypeSafe AI emerges from stealth with $40M
- The Register: TypeSafe AI debuts model for machines that plays Doom
- Sean Goedecke: Jev means structured output is interesting again
// About the author
Remy Gieling
Mede-oprichter, AI-expert & bestseller-auteur
Tech-expert (1988) gespecialiseerd in kunstmatige intelligentie en mede-oprichter van ai.nl, The Automation Group, Proxies en eBrain.ai. Oud-hoofdredacteur van diverse zakenmerken en daardoor een geoefend verteller op het podium en in de media. Verzorgt jaarlijks 150+ AI-keynotes in binnen- en buitenland en is gastdocent aan Nyenrode. Co-auteur van zeven boeken, waaronder 'Handboek AI Strategie' en 'AI Agents', en bekend als presentator op radio en RTL Z. Reist langs de labs van OpenAI, Nvidia en Tencent en vertaalt de nieuwste doorbraken naar inzichten die leiders direct kunnen toepassen.
LinkedIn